Why I Still Choose Static-First Websites in 2026
I explain why I keep choosing static-first for blogs, docs, and portfolios, what it costs, and when I pay for a server instead.
Thoughts on modern web development, architecture, and design.
I explain why I keep choosing static-first for blogs, docs, and portfolios, what it costs, and when I pay for a server instead.
The skills that move engineers from junior to senior aren't just technical. Here's what engineering culture research actually shows about leveling up.
I lay out the learning path I'd follow from scratch: the specific order, what to spend time on, what to skip, and where AI tools actually fit in.
I walk through XSS, CSRF, and SQL injection from the attacker's side — the mechanics, the targets, and the code patterns that signal an exploitable application.
I break down five JWT misconceptions — localStorage risk, short expiry, revocation, algorithm confusion attacks, and the statelessness myth — and show when session tokens win.
I compare PostgreSQL and MongoDB across data model, schema flexibility, transactions, query power, and scaling — so you can choose based on your actual situation, not the hype.
I argue that starting with microservices is a mistake for most teams, explain why the modular monolith is the smarter default, and show when distributed services genuinely earn their cost.
I walk through ten REST API mistakes that keep showing up in real codebases — wrong methods, missing pagination, no idempotency, leaking errors — and show the concrete fix for each.
I walk through 10 CLI and desktop tools — from ripgrep and fzf to lazygit and Bruno — each with a concrete use case for the problems they actually solve.
A verified list of 10 VS Code extensions — from ESLint and GitLens to Error Lens and REST Client — with their actual use cases and what each one covers that VS Code's defaults don't.
I walk through 10 GitHub repositories worth bookmarking — from interactive learning roadmaps to local AI tools — each with a specific reason to use it and how.
A practical comparison of Rust and Go for backend developers — covering performance, concurrency models, learning curve, and job market so you can choose the right one.
I look at the Stack Overflow survey streak, what the admiration score actually measures, why practitioners cite correctness over performance, and where Rust is already running in production.
I explain what HTMX does differently, show how hx-get and hx-swap work, and give an honest account of where it outperforms React and where it doesn't.
I look at Bun's verified speed claims, Node.js compatibility as of early 2026, where it genuinely saves time, and which gaps still block a clean switch.
I explain why webpack's bundle-first approach gets slow at scale and how Vite's native ESM model changes the dev server experience for most projects.
I compare Vite's native ESM dev server to the bundle-first approach of webpack, explain the real performance difference, and walk through migrating from CRA step by step.
I explain what shadcn/ui's copy-paste model actually means, how Radix UI handles accessibility under the hood, and what changes when you own your UI code.
I explain how React and Next.js relate, what the framework adds on top of the library, and give you a concrete guide for which to start with based on what you're actually building.
I walk through the two breaking changes in Next.js 15 — async request APIs and the new caching defaults — explain the React 19 requirement, and help you decide if it's time to upgrade.
I cover the meaningful changes in React 19 — Actions, useActionState, the use() hook, React Compiler, document metadata, ref as prop, and how to upgrade.
I walk through the adoption data, the practical day-to-day wins, the native compiler story, and the honest cases where plain JavaScript still makes more sense.
I look at State of JS 2024, Stack Overflow data, and GitHub Octoverse to explain why JavaScript isn't dying — but it is changing in ways worth understanding.
Python topped GitHub's language rankings in 2024, ending JavaScript's decade-long run. I dig into the data, the causes, and what it actually means for JS developers.
I walk through running open-weight language models on a laptop using Ollama, explain what GGUF quantization is, and show you which model sizes actually fit in consumer RAM.
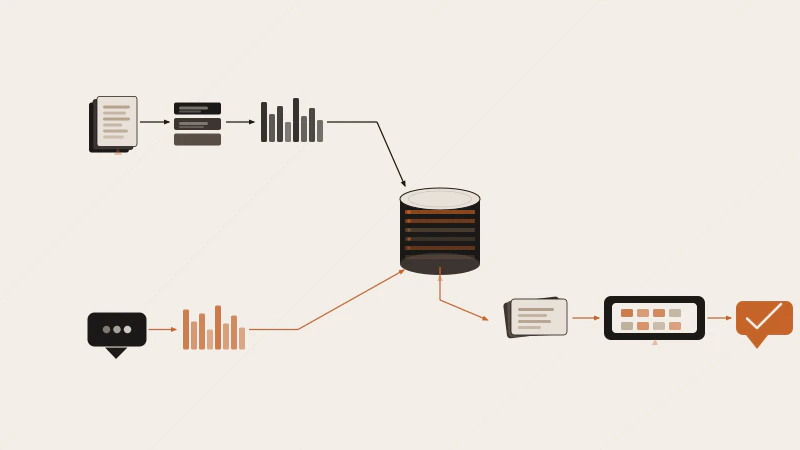
I explain how Retrieval-Augmented Generation works from embeddings to the retrieval step, then show a minimal TypeScript pipeline that chunks, stores, and retrieves your own documents before calling the LLM.
I walk through building a streaming chat app end to end — Express proxies the OpenAI API key server-side, pipes SSE chunks back, and a React UI reads and renders each token as it arrives.
I walk through 10 tested prompt templates for debugging, code review, testing, and documentation, and explain the structure behind why each one actually works.
I look at documented public experiments — gpt-engineer, smol-dev, and real developer workflows — to show where AI-generated apps shine, where they fall apart, and what the job shift means in practice.
Here's what actually separates these two AI coding tools — context depth, agent capabilities, and pricing — so you can pick based on your workflow, not marketing claims.
I look at what the research says about AI and developer productivity, where certain roles are genuinely at risk, and what is actually worth preparing for.
I map out four skills worth real investment in 2026 — AI tooling depth, Rust fundamentals, end-to-end type safety, and system design — with honest reasons behind each choice.
Six honest lessons from 2025 — TypeScript as the new floor, the Vite tooling win, AI's productivity ceiling, and where meta-framework complexity actually lives.
I walk through setting up npm/bun scripts, Husky pre-commit hooks, and lint-staged so your project checks code quality on every commit without slowing down the process.
I walk through the three observability signals — structured logs, metrics, and distributed traces — and show how to set up Pino in Node.js.
I walk through the architecture behind a multi-channel notification system — fan-out, templates, delivery guarantees, and user preferences — and show where the non-obvious decisions sit.
I walk through designing a URL shortener from requirements to caching, covering ID generation, the 301-vs-302 redirect decision, and scaling the read path.
I break down what load balancers, application caches, and CDNs each do, how L4 vs L7 routing differs, why sticky sessions are a trap, and when to use Redis vs a CDN.
I walk through the real arc from a single-server app to a distributed system, showing where each stage breaks and what each layer of the architecture actually fixes.
I walk through FlatList vs ScrollView for long lists, useCallback and React.memo for list items, InteractionManager for deferring heavy work after animations, the Hermes engine, and how to profile with React Native DevTools.
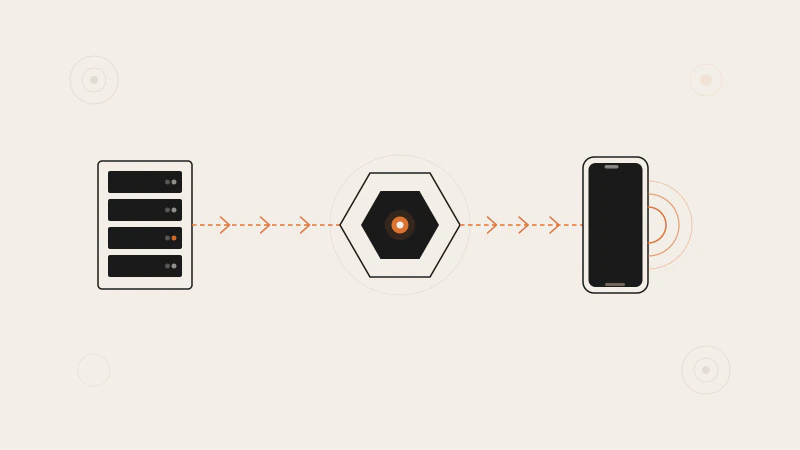
I trace the full path a push notification takes from server to screen — APNs, FCM, the Expo push service — and show how to handle permissions, tokens, and messages in three different app states.
I explain the two React Native deep linking approaches — custom URL schemes and HTTPS universal links — and show how to wire both into React Navigation.
I cover token storage security in React Native, the access and refresh token pattern, navigation-based auth guards, biometric auth as a device gate, and OAuth with Expo's WebBrowser.
I cover TextInput's controlled input model, keyboard types, react-hook-form's Controller pattern, and Zod schema validation in React Native — plus the accessibility props that replace HTML label elements.
I cover the four state layers in a React Native app — local state, Context, Zustand, and AsyncStorage — and show what's different from managing state in web React.
I walk through React Navigation setup in React Native — Stack, Tab, and Drawer navigators, typed params, a deep links primer, and when Expo Router makes more sense.
I map out what transfers from React to React Native — JSX, hooks, props — and what changes — native views, StyleSheet, the flexbox defaults — so you can build your first mobile screen with confidence.
I walk through how to debug a slow API endpoint using RUM data, Node.js CPU profiles, flamegraphs, and database slow query logs — a step-by-step process for finding what's actually slow.
I show which next/image props actually change what the browser downloads, how next/font eliminates layout shift by default, and how caching strategy directly controls your page's TTFB.
I explain how dynamic import() tells your bundler to split code, show how React.lazy and Suspense work together, and cover the patterns that actually improve initial load time.
I walk through the React DevTools Profiler to find slow components, explain React.memo, useCallback, and useMemo, and show when to skip memoisation entirely.
I walk through how to keep secrets out of git, wire them securely into CI/CD pipelines, and know when a dedicated secrets manager is worth the complexity.
I walk through rate limiting, CORS, and Helmet security headers for Express — covering fixed windows, preflight handling, and the 13 headers Helmet sets by default.
I walk through the concrete defenses for XSS, CSRF, and SQL injection — output encoding, CSP, SameSite cookies, CSRF tokens, and parameterized queries — with working TypeScript code examples.
I walk through the security mindset that underpins every defence — the OWASP Top 10 reframed for developers, threat model thinking, defence in depth, and secure defaults.
I cover Cypress E2E setup, the core commands, data-cy selectors, cy.intercept for network stubbing, CI integration, and when E2E tests are worth writing.
I explain how Supertest sends HTTP requests to an Express app in tests, covering endpoint organization, auth header mocking, and database test strategies.
I walk through Vitest setup, the AAA pattern, vi.fn() mocks, module mocking, snapshot testing, and coverage — with the common mistakes that make tests brittle.
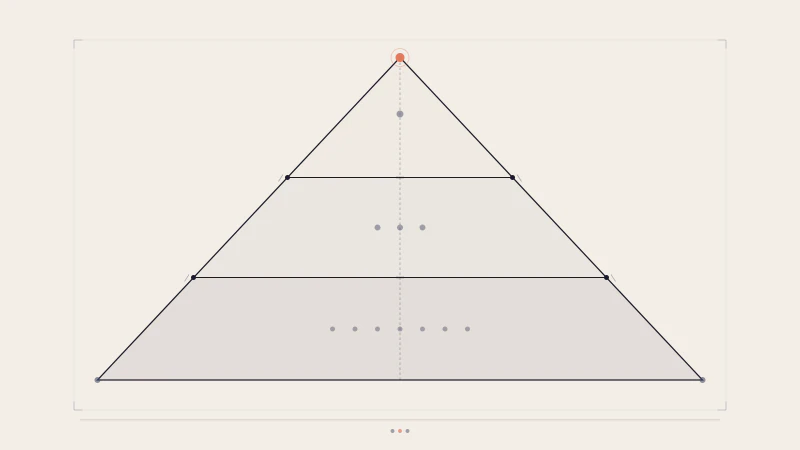
I walk through the testing pyramid, explain what unit, integration, and E2E tests each verify, and share the tradeoff that decides which layer a test belongs in.
I walk through how to share Zod schemas between frontend and backend, why runtime validation at API boundaries matters, and when OpenAPI codegen is the better fit.
I explain how tRPC enforces API type safety without code generation, show how routers and procedures work, and cover when to use it over REST or GraphQL.
Schema-first design with Apollo Server — type definitions, resolver arguments, the context object, mutations, subscriptions, and DataLoader to prevent the N+1 problem.
A practical comparison of GraphQL and REST — covering over-fetching, the schema type system, the N+1 problem, HTTP caching, and a situation-based recommendation for each.
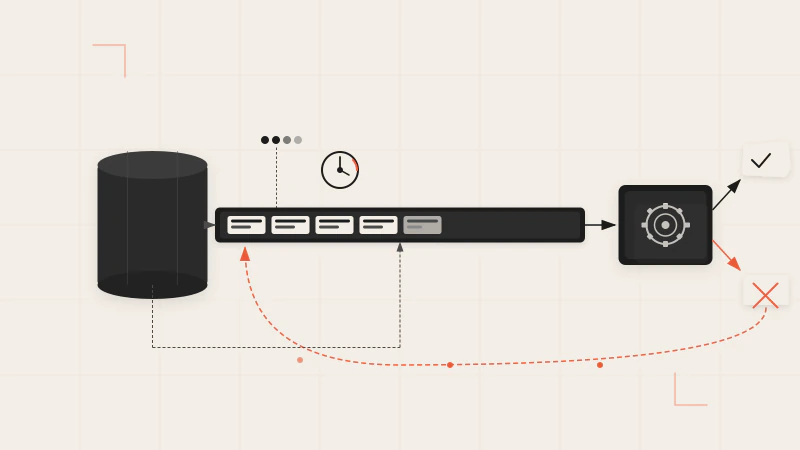
I walk through BullMQ's Queue, Worker, and QueueEvents APIs, show how retries and backoff work, and cover the dead-letter queue pattern for failed jobs.
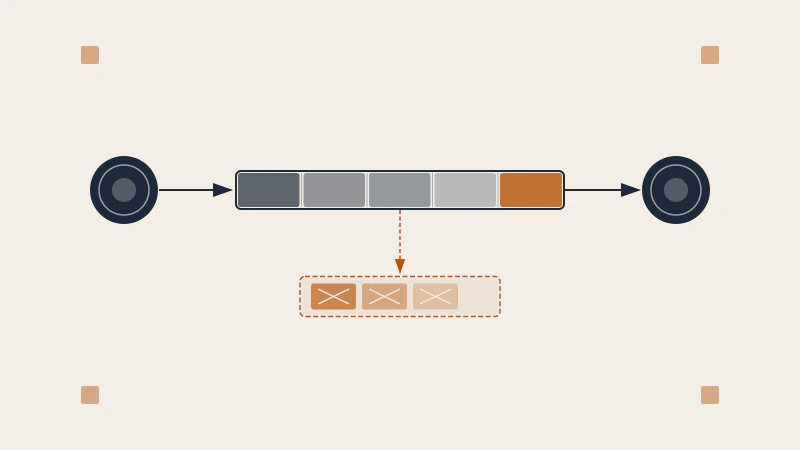
I explain why background jobs exist, how the producer/consumer pattern works, and what queue semantics and delivery guarantees mean for a Node.js backend.
I walk through four application cache patterns, HTTP Cache-Control and ETags, and CDN caching — explaining when each approach genuinely helps and when it makes things worse.
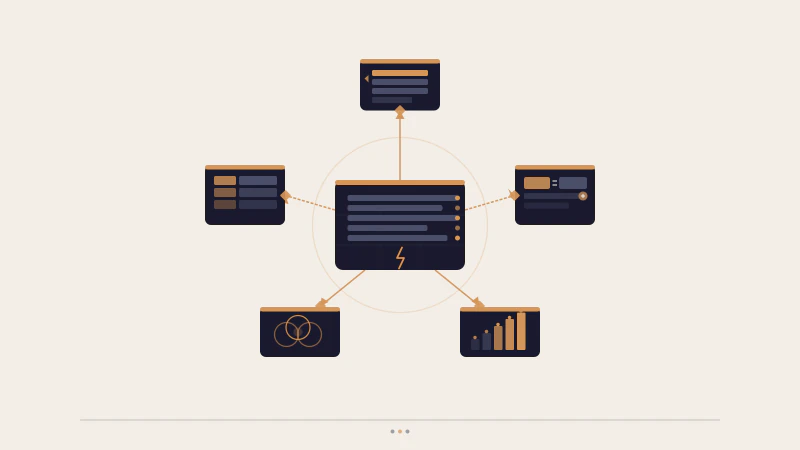
I walk through Redis data structures, TTL, the four main use cases, and RDB vs AOF persistence to give you the mental model before caching strategies.
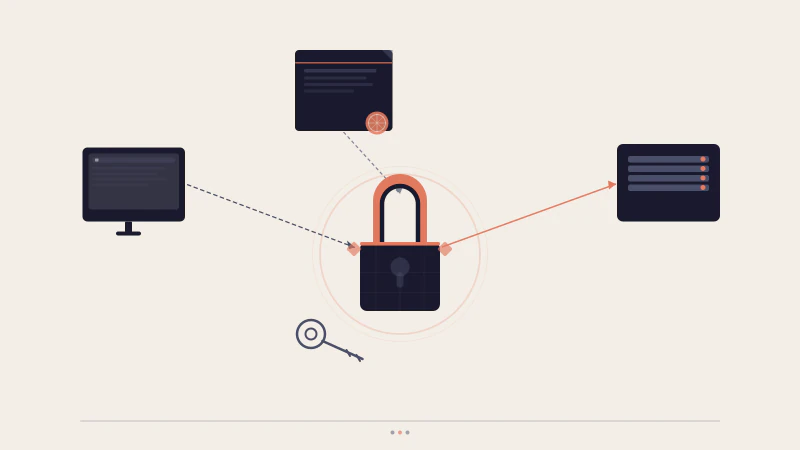
I explain the TLS handshake and certificate chain, then show the Certbot workflow and nginx config to get HTTPS running on a real domain.
I explain what a reverse proxy is, walk through the core nginx blocks, and show how to add load balancing, gzip, and rate limiting to a production config.
I walk through launching an EC2 instance, setting up PM2 as a process manager, and configuring nginx as a reverse proxy for a Node.js API.
I walk through the seven AWS services a full-stack developer reaches for on almost every project — EC2, Lambda, S3, RDS, CloudFront, IAM, and VPC — and explain when to use each one.
I walk through building a GitHub Actions pipeline for a Node.js app — triggers, install steps, npm ci, caching node_modules, and environment secrets.
I walk through how a CI/CD pipeline works — from git push through build, test, and deploy stages — and explain the real distinction between continuous integration, delivery, and deployment.
I walk through ConfigMaps and Secrets in Kubernetes — how they differ, why base64 isn't encryption, and the two ways to expose them to containers.
I explain the three Kubernetes building blocks every developer needs — Pods, Deployments, and Services — and show how they fit together as a practical mental model.
I show how one Docker Compose file connects a frontend, API, and database — covering service names as hostnames, per-service env vars, and dev versus prod override files.
I walk through building a local app-and-database stack with Docker Compose, covering the compose.yaml structure, healthchecks, volume mounts for hot-reload, and named volumes for persistence.
I show how Docker layer caching, the COPY package.json trick, multi-stage builds, and a non-root user turn a messy Dockerfile into a lean, production-safe image.
I break down the image vs container mental model, walk through docker pull and the docker run flags you'll use daily, cover volumes and port mapping, and show you how to manage containers with ps, logs, stop, and rm.
I walk through Go's error-as-value pattern — errors.New, fmt.Errorf with %w, errors.Is, custom error types — and show how cmd/, internal/, and pkg/ structure a real Go project.
Walk through building a working REST API in Go with Gin — routes, groups, middleware, JSON binding, and consistent error responses.
I explain Go's goroutine model, show how channels handle synchronization, and cover buffered channels, the select statement, and WaitGroup with code and JS comparisons.
I walk through Go's type system, variables, packages, the three-command toolchain, and multiple return values — with honest comparisons for developers who know Node.js.
I break down Rust's module system — the package vs crate distinction, mod, pub, use, path visibility, and how to publish your first crate on crates.io.
I walk through std::env::args, clap's derive API, splitting logic across main.rs and lib.rs, reading files, and using the ? operator in main to build a working word-counter CLI.
I walk through Vec<T>, the String vs &str distinction, and HashMap<K,V> with the entry API — covering the ownership pitfalls TypeScript developers hit first.
I walk through Rust's Result<T,E> and Option<T> types, the ? operator, pattern matching on error variants, and custom error types with the thiserror crate.
I walk through Rust generics and traits — generic functions, structs, enums, trait definitions, bounds, where clauses, and the standard library traits you will use in every Rust program.
I walk through Cargo.toml's key sections, how Rust's module system works with mod, use, and pub, how workspaces compare to monorepos, and the cargo commands you'll run every day — from a TypeScript developer's perspective.
I break down Rust's match expression — exhaustiveness, destructuring, guards, and if let — and compare each to the TypeScript patterns they replace.
I walk through Rust's if/else expressions, three loop types, classic and tuple structs, data-carrying enums, and impl blocks — with comparisons to TypeScript interfaces and discriminated unions.
I walk through Rust's immutable-by-default variables, shadowing, scalar and compound types, and the expression rule that defines how functions return values.
I break down Rust's ownership model — how single ownership, move semantics, and borrows (&T and &mut T) prevent memory bugs that other languages catch too late.
I walk through installing Rust with rustup, what Cargo does, the key fields in Cargo.toml, and wiring up rust-analyzer in VS Code so you can write Rust without fighting the toolchain.
Why I started learning Rust after years with TypeScript, what the ownership model actually means, and what to expect from this 12-part series.
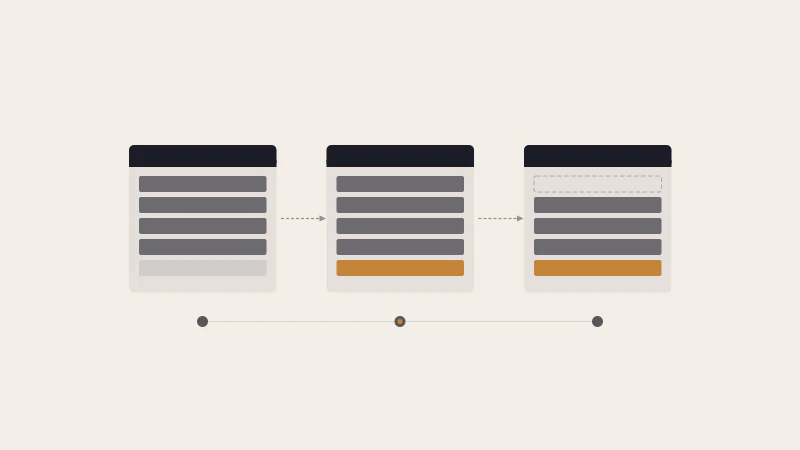
The expand/contract pattern lets you rename or drop columns safely — I walk through the three phases with Prisma Migrate and raw SQL examples.
I walk through Prisma's schema file, generated client, CRUD operations, and relations, with a focus on how it integrates with TypeScript to give you compile-time safety on every database query.
I walk through what a PostgreSQL transaction actually guarantees, break down each ACID property with a plain analogy, and explain isolation levels and the pitfalls that trip up most teams.
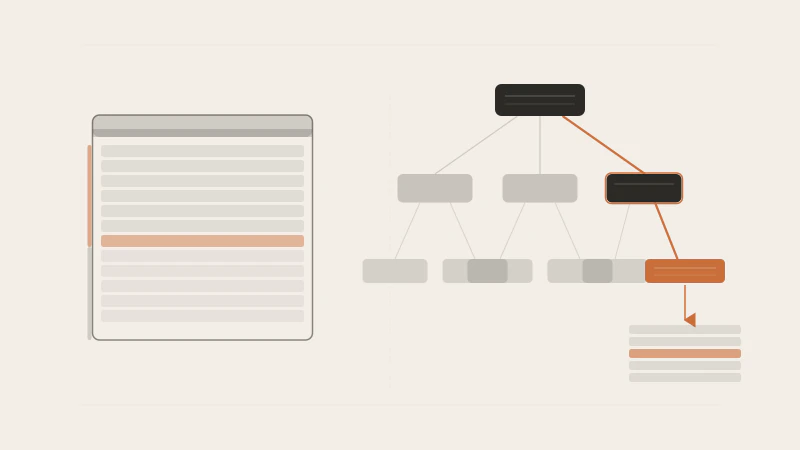
I walk through how PostgreSQL B-tree indexes work, how to read EXPLAIN ANALYZE to confirm what the planner actually does, and the indexing mistakes that cancel out the gains.
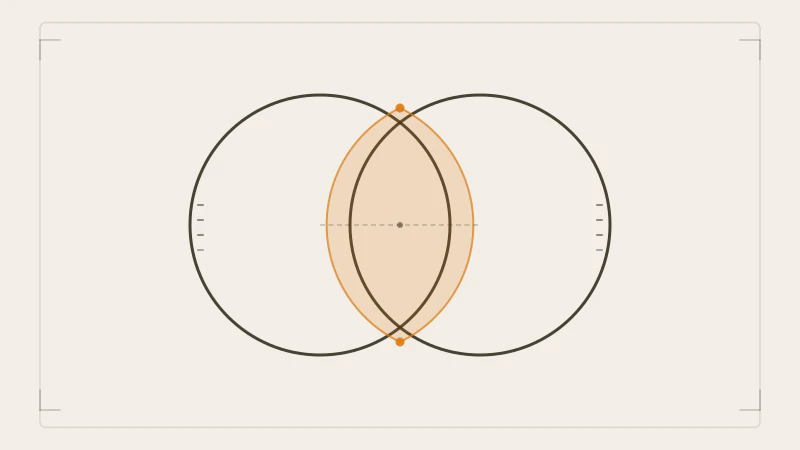
I explain each PostgreSQL join type with working examples, show exactly what rows each one returns, and cover the NULL pitfalls most developers hit first.
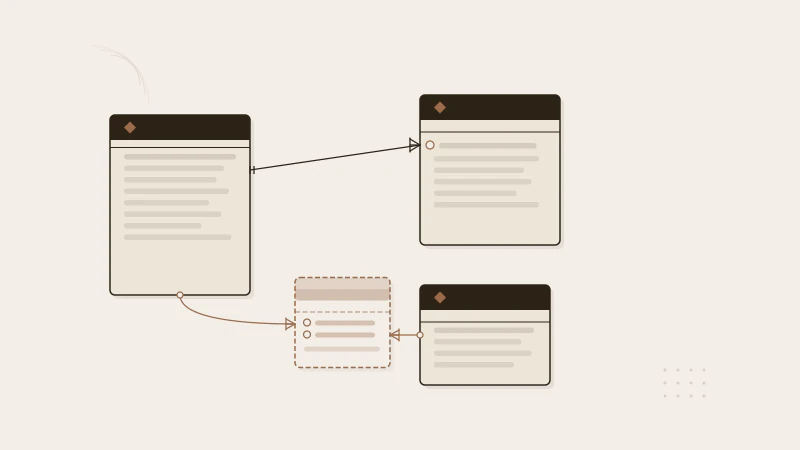
I walk through PostgreSQL tables, data types, primary and foreign keys, one-to-many and many-to-many relationships, and basic CRUD for JavaScript developers building their first schema.
I walk through JWT structure, signing tokens with jsonwebtoken, writing a verify middleware for Express, the refresh token pattern, and where to store tokens safely.
I break down authentication and authorization — who you are vs what you can do — covering sessions, JWTs, RBAC, and why OAuth 2.0 naming confuses everyone.
I explain how Express routes errors to a centralized handler, the difference between operational and programmer errors, and what changed in Express 5.
I explain how Express middleware works — the req/res/next signature, execution order, built-in and third-party options, and real patterns for auth and logging.
I walk through the Express folder layout that scales — separating routes, controllers, services, and middleware into layers with one job each.
Set up an Express 5 server, define routes for each HTTP method, wire the middleware your API needs, and test everything without writing a frontend.
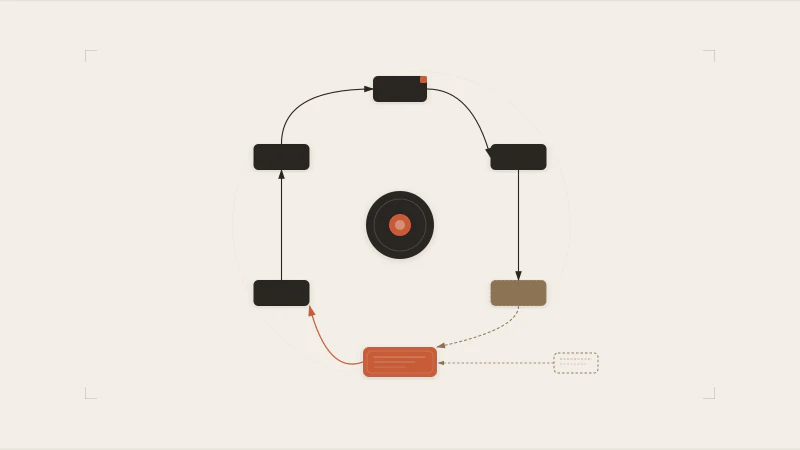
I walk through libuv's six phases and show exactly when process.nextTick(), setImmediate(), and promise callbacks run in the Node.js event loop.
I break down how Node.js works under the hood — V8's JIT compilation, libuv's async I/O, and when to choose CommonJS over ESM.
I walk through how route.ts works, when to choose it over Server Actions, and the API design patterns that hold up as a Next.js app grows.
I walk through the session-based architecture for Next.js 15 authentication — setting up Auth.js, choosing between stateless and database sessions, and protecting routes with middleware.
I cover static and dynamic metadata in the App Router, how to generate OG images, and why JSON-LD needs a native script tag rather than next/script.
I explain the three Next.js cache layers and show which tool — fetch options, React.cache, unstable_cache, revalidatePath, or revalidateTag — fits each situation.
I walk through how the 'use client' directive marks a module boundary — not a rendering flag — and give you a practical mental model for composing Server and Client Components in Next.js.
I explain how the App Router works in Next.js — file conventions, nested layouts, Server vs Client Components, and what changed from the Pages Router.
A practical guide to controlled inputs, validation patterns, and using react-hook-form with Zod or Yup — covering error timing, server-side failures, and the submit state that most forms forget.
A decision guide comparing useState, Context, Redux Toolkit, and Zustand — covering re-render trade-offs, when each tool fits, and the one Context surprise that trips up most developers.
The design principles that make a React component truly reusable: prop interfaces, the children pattern, controlled APIs, and warning signs of over-engineering.
A deep-dive into useEffect — the correct mental model, the cleanup contract, stale closures, and when to reach for something else entirely.
A practical walkthrough of useState, useEffect, useCallback, useMemo, useRef, and useContext — with the gotchas that cause real bugs and when each hook genuinely pays off.
I explain the three mental models behind React — UI as a function of state, one-way data flow, and state colocation — through components, props, and useState.
Small teams don't need Gitflow's overhead. I explain branch naming, commit discipline, rebase vs merge, and why long-lived branches—not Git—cause merge pain.
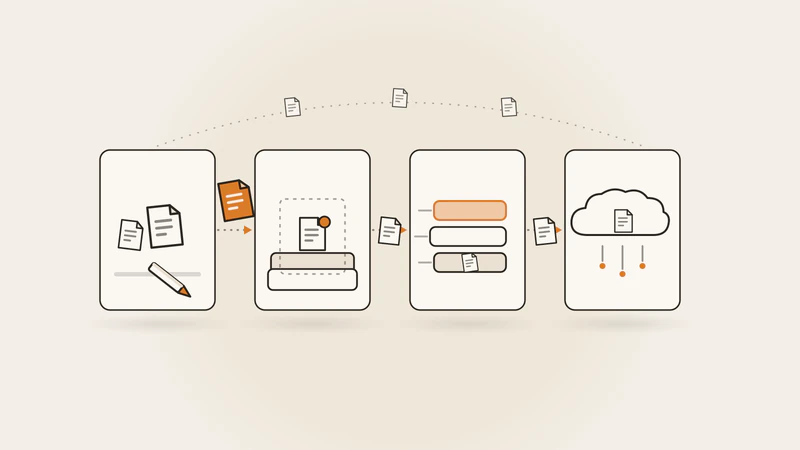
I explain the four places your code lives in Git — working tree, staging area, repository, remote — and the daily commands that finally make sense once you see the map.
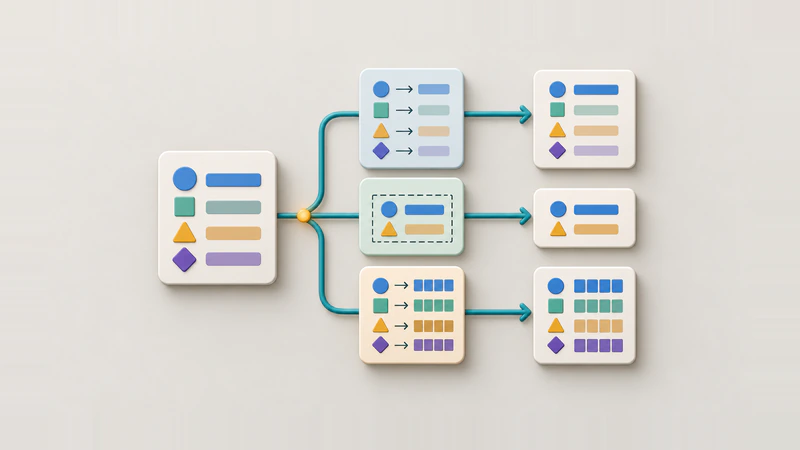
I tour the TypeScript utility types worth using daily — Partial, Pick, Omit, Record, ReturnType and friends — with the real shapes they replace and where they stop helping.
I explain TypeScript generics as functions for types — from the duplication they replace to constraints, defaults, inference, and why they vanish at runtime.
I compare TypeScript interfaces and type aliases on the differences that actually matter — naming, merging, and error messages — and give a simple decision rule.
I explain the contract mindset behind TypeScript's checks, the annotations worth learning first, and how to migrate a JavaScript file one rename at a time.
I explain the array methods worth knowing by the three questions they answer — transform, select, reduce — plus the mutate-in-place fault line that bites everyone.
I explain the browser's event loop, the difference between tasks and microtasks, and how promises and async/await schedule their work on those queues.
I explain what a JavaScript closure really captures, why returned functions still reach outer variables, and the loop bug and memory cost that catch people out.
I explain what a JavaScript execution context holds, its two phases, the scope chain and the call stack, and why hoisting falls straight out of the model.
I explain how to build responsive layouts with intrinsic sizing, fluid spacing, and container queries instead of a growing pile of breakpoints.
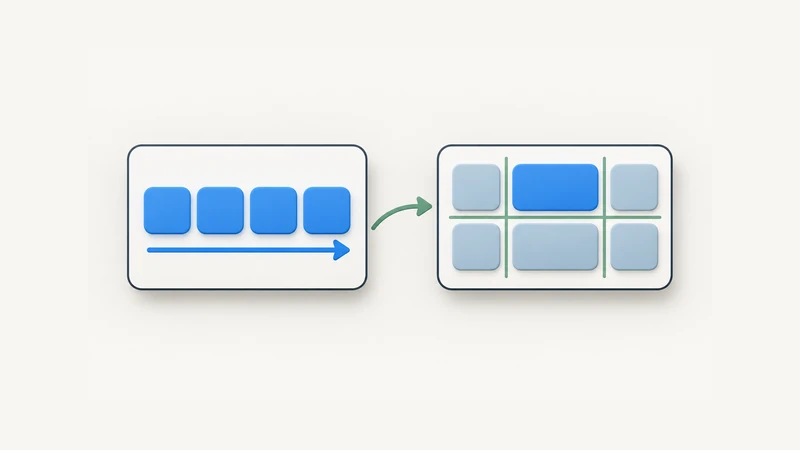
I explain the core difference between CSS Flexbox and Grid, show when each one is the better choice, and cover how to use both in the same layout.
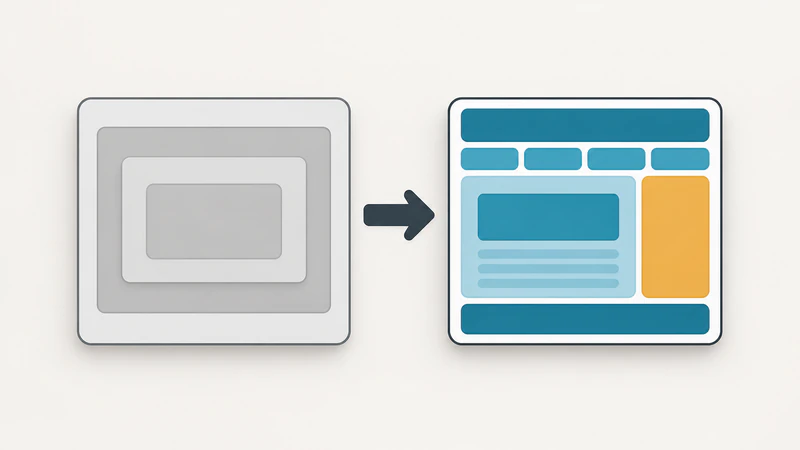
I cover the HTML semantic elements that replace generic divs, explain when to use each one, and show how they improve accessibility and page structure.
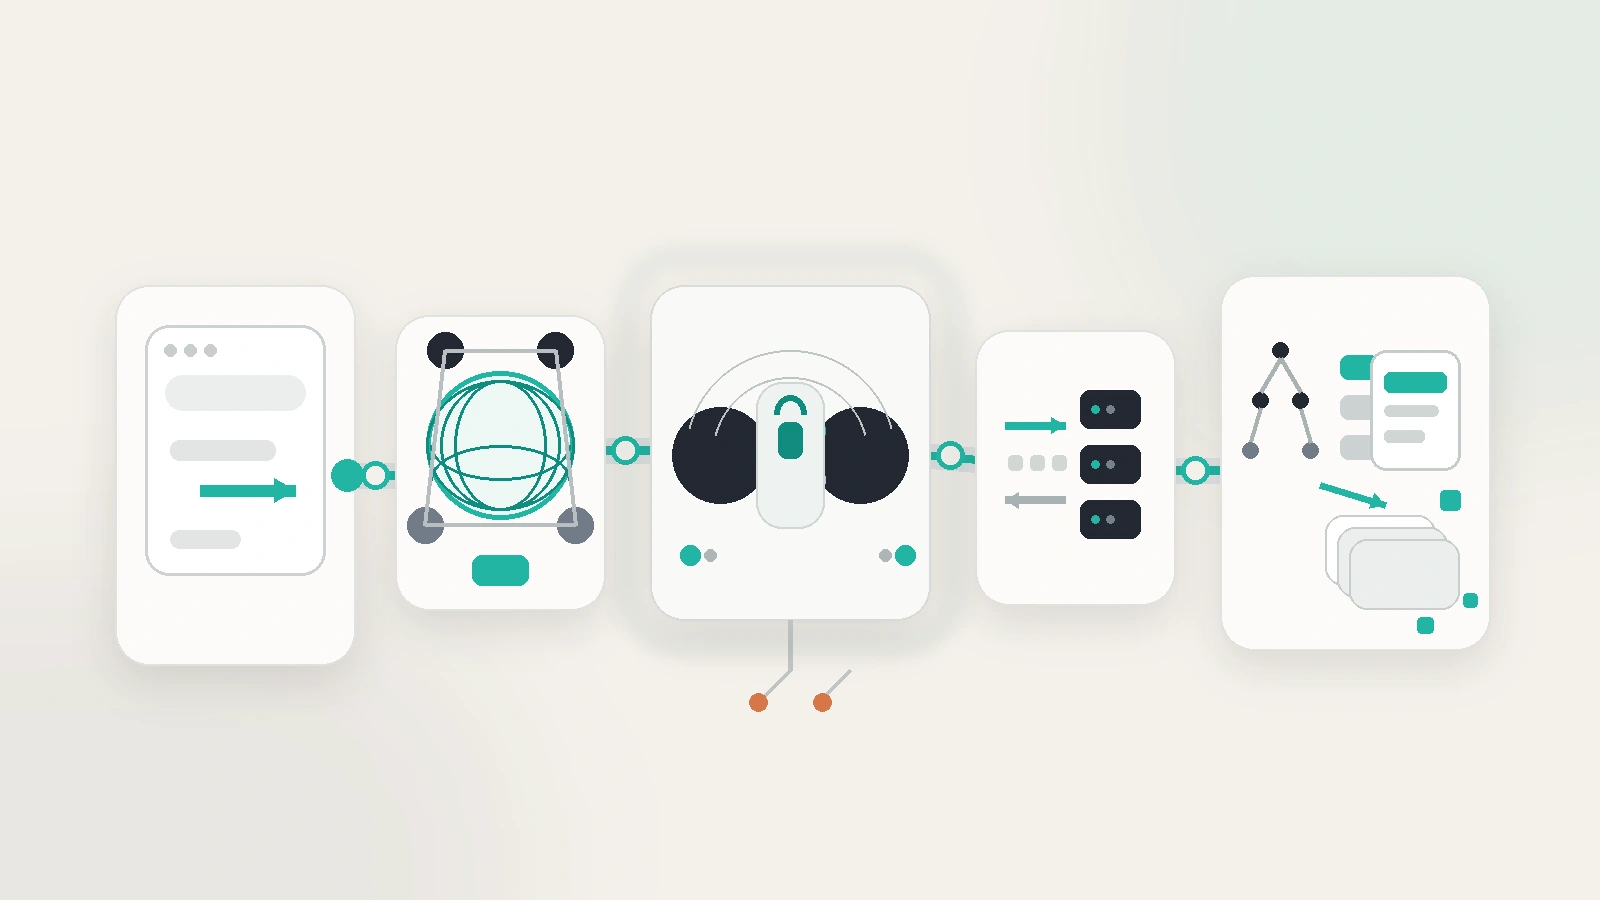
I walk through every step between typing a URL and seeing a page, from DNS lookups and TCP handshakes to HTML parsing and the first paint.