Caching Strategies That Improve API Performance
I walk through four application cache patterns, HTTP Cache-Control and ETags, and CDN caching — explaining when each approach genuinely helps and when it makes things worse.
Most advice about API caching goes straight to tooling: add a key-value store, get performance. But choosing a caching tool before choosing a caching pattern is backwards. The pattern determines how data enters the cache, how it stays current, and what happens when it’s wrong.
There are four application-level cache patterns, each with different trade-offs. Layer in HTTP caching and CDN caching, and you have a complete picture of how fast APIs actually work. I’ll walk through each one and explain the conditions where it fits — so when you reach for a cache, you’re reaching for the right one.
On this page
- When caching actually makes sense
- Cache-aside: the most common pattern
- Read-through and write-through
- Write-behind: trading durability for throughput
- HTTP caching: Cache-Control and ETags
- Cache invalidation: where implementations break
- Pick the pattern before you pick the tool
When caching actually makes sense
Caching works best on data that is read frequently but changes infrequently. A product catalog queried thousands of times per hour but updated once a day is a strong candidate. A user’s session state, modified on every action, is a weak one.
Before adding a cache, two questions are worth answering:
- How often does this data change? If a record updates every few seconds and your TTL is 60 seconds, you’re serving stale data almost continuously.
- How often is this data read? Caching a rarely accessed endpoint saves almost nothing. Caching an endpoint that accounts for 60% of your database queries can transform response times.
The clearest signal is a read-heavy endpoint with a slow but stable query. If the same result would be valid for the next five minutes on 90% of requests, caching it for five minutes is probably safe.
Worth noting: caching delays your database, it doesn’t replace it. If the cached value is wrong, every client gets the wrong answer until expiry or explicit invalidation. That cost is real, and it’s worth factoring in before treating a cache as automatically “safe.” This is the same kind of trade-off as database indexing — done right, it speeds things up considerably; done carelessly, it creates subtle problems that are painful to track down.
Cache-aside: the most common pattern
Cache-aside (sometimes called lazy loading) is the most widely used pattern. The application owns the cache logic directly:
- Check the cache for the requested key.
- On a cache hit, return the cached value immediately.
- On a cache miss, query the database, write the result to the cache, then return it.
Here’s what that looks like in a Node.js service:
async function getProduct(id: string): Promise<Product> {
  const key = `product:${id}`;

  const hit = await cache.get(key);
  if (hit) return JSON.parse(hit) as Product;

  const product = await db.products.findById(id);
  await cache.set(key, JSON.stringify(product), 300); // 5-minute TTL
  return product;
}
The advantage is that only data that actually gets requested ends up in the cache — you’re not pre-loading records that nobody reads. The downside is the cold start: the first request after a miss or server restart always hits the database.
Under high concurrency, multiple requests can reach the database simultaneously for the same key before any of them populates the cache. This is the “thundering herd” problem. The standard mitigation is a short distributed lock that allows only one request to populate the key while the others wait briefly and then read from the freshly populated cache.
Cache-aside also means your code is responsible for key naming, TTL decisions, and invalidation. That’s workable for a small service and becomes a maintenance burden at scale. If you’re building a REST API in Node.js, cache-aside is often the first pattern you’ll reach for — and usually the right one for most endpoints.
Read-through and write-through
Read-through and write-through patterns move the cache logic out of the application and into a dedicated layer that sits between your code and the database.
Read-through means the application only ever reads from the cache. On a miss, the cache layer itself fetches from the database, populates itself, and returns the result. The application doesn’t know a miss happened. This simplifies application code but requires a cache library or service that supports the pattern natively.
Write-through pairs with read-through: every write goes to the cache first, which then writes synchronously to the database before confirming success. After any write, the cache is always up to date — there’s no stale window between a write and cache expiry.
The cost is write latency. Write-through waits for both the cache write and the database write before returning to the caller. For read-heavy workloads where stale data is unacceptable, that overhead is usually worth paying. For write-heavy workloads, it adds up quickly.
Write-through also solves the cold-start problem that cache-aside has. Because writes always populate the cache, the cache is warm for subsequent reads — no thundering herd on startup.
Check this before moving on
- You can explain why cache-aside has a cold-start problem and write-through doesn’t
- You understand that write-through adds latency on every write, not just reads
- You know that read-through moves cache logic out of your application code
Write-behind: trading durability for throughput
Write-behind (also called write-back) makes the database write asynchronous. The application writes to the cache, the cache acknowledges immediately, and the actual database write happens in the background.
This is the fastest write pattern — the application doesn’t wait for the database at all. For workloads with extremely high write throughput (counters, leaderboard updates, analytics events), write-behind can dramatically reduce database pressure.
The risk is data loss. If the cache node fails before flushing to the database, those queued writes are gone. For financial records, user accounts, or any data where durability is non-negotiable, write-behind is dangerous. For approximate metrics or events where losing a small fraction is acceptable, it’s a practical choice.
I’d put it this way: before using write-behind, answer explicitly — “what does it cost us to lose 30 seconds of writes?” If the answer is anything other than “not much,” use write-through instead.
HTTP caching: Cache-Control and ETags
HTTP caching operates at the protocol level. Rather than your application managing a cache store, you use response headers to tell browsers, reverse proxies, and CDNs what to store and for how long. This is the layer that makes static assets load instantly on repeat visits — and the layer that makes APIs feel snappy for clients that understand conditional requests.
The key header is Cache-Control:
# Versioned static asset — cache for one year, no revalidation needed
Cache-Control: public, max-age=31536000, immutable

# API response — allow caching but always validate before reuse
Cache-Control: no-cache

# User-specific or sensitive data — never store in shared caches
Cache-Control: private, no-store
One misread that trips people up: no-cache does not mean “don’t cache.” It means “store this response, but check with the origin server before reusing it.” The check is a conditional request using either Last-Modified / If-Modified-Since or an ETag / If-None-Match pair. If the content hasn’t changed, the server returns 304 Not Modified with no body — saving bandwidth without a full round trip. If you want to truly prevent storage, use no-store.
For CDN caching specifically, s-maxage lets you set a longer lifetime in shared caches while controlling the browser separately. s-maxage=3600 tells a CDN to cache the response for an hour even if max-age is shorter or absent.
ETags are useful on JSON APIs. You hash the response body, set it as the ETag, and on subsequent requests check whether the client already has the current version:
import crypto from "node:crypto";

app.get("/api/products/:id", async (req, res) => {
  const product = await getProduct(req.params.id);
  const etag = `"${crypto.createHash("sha1").update(JSON.stringify(product)).digest("hex")}"`;

  res.set("ETag", etag);
  res.set("Cache-Control", "no-cache");

  if (req.headers["if-none-match"] === etag) {
    return res.status(304).end();
  }

  res.json(product);
});
The client sends the ETag back on subsequent requests in If-None-Match. If the hash matches, you skip the response body entirely — the client already has the right version. This is particularly useful for endpoints that return large JSON payloads where the data changes infrequently.
For a well-structured Express project, the standard practice is to include version hashes in static asset filenames (cache busting) and set max-age=31536000, immutable. For the HTML document itself, use no-cache so clients always revalidate before rendering potentially stale markup.
Cache invalidation: where implementations break
Cache invalidation is the part of caching where most real-world problems hide. When data changes in the database, the cache doesn’t know. Clients receive the old version until the TTL expires or something explicitly clears the key.
Three strategies exist:
TTL-based expiry. Set a TTL and let entries expire naturally. Simple to implement, but stale data is guaranteed for up to TTL seconds after every write. A 5-minute TTL means up to 5 minutes of incorrect answers after any update. For data that changes rarely, this is fine. For data that changes often, it’s quietly wrong.
Event-driven invalidation. When data changes, explicitly delete or update the relevant cache entry in the write path. This closes the stale window entirely. The cost is that your write code needs to know which cache keys to invalidate. For simple schemas (one key per user, one key per product), this is straightforward. For data that feeds many different cached responses, it becomes fragile — a single user record might appear in a dozen different cached endpoints.
Versioned keys. Instead of invalidating, move to a new key when data changes: product:123:v2 instead of product:123. The old key expires on its TTL. This is safe and simple but grows cache memory without a cleanup strategy.
The most common mistake is choosing a TTL that’s longer than the data’s change rate, because long TTLs feel safer. A product price that changes hourly should not have a 24-hour TTL. If you’re unsure about the right TTL, start short — you can always increase it once you’ve confirmed how often the underlying data actually changes.
Pick the pattern before you pick the tool
The store you use for caching — whether it’s a local in-process map, a distributed store like Redis, or just HTTP headers — matters less than choosing the right pattern for your workload.
For read-heavy data that rarely changes: cache-aside with a conservative TTL is usually the right starting point. For workloads where stale data after a write is unacceptable: write-through. For write-heavy systems where losing a small amount of data is acceptable: write-behind (carefully, and only after answering the durability question explicitly). For APIs serving the same response to many clients: HTTP Cache-Control with ETags. For global edge performance: CDN caching with s-maxage.
What ties all of these together is invalidation. Before picking a pattern, decide: “When does this data become invalid, and what triggers the update?” If the answer is “when the TTL expires,” make sure that TTL matches how quickly the underlying data actually changes.
Caching done deliberately — right pattern, right TTL, clear invalidation strategy — makes APIs faster and reduces database load with minimal added complexity. Caching done carelessly, with long TTLs and no invalidation plan, creates correctness bugs that are difficult to reproduce and painful to fix in production.
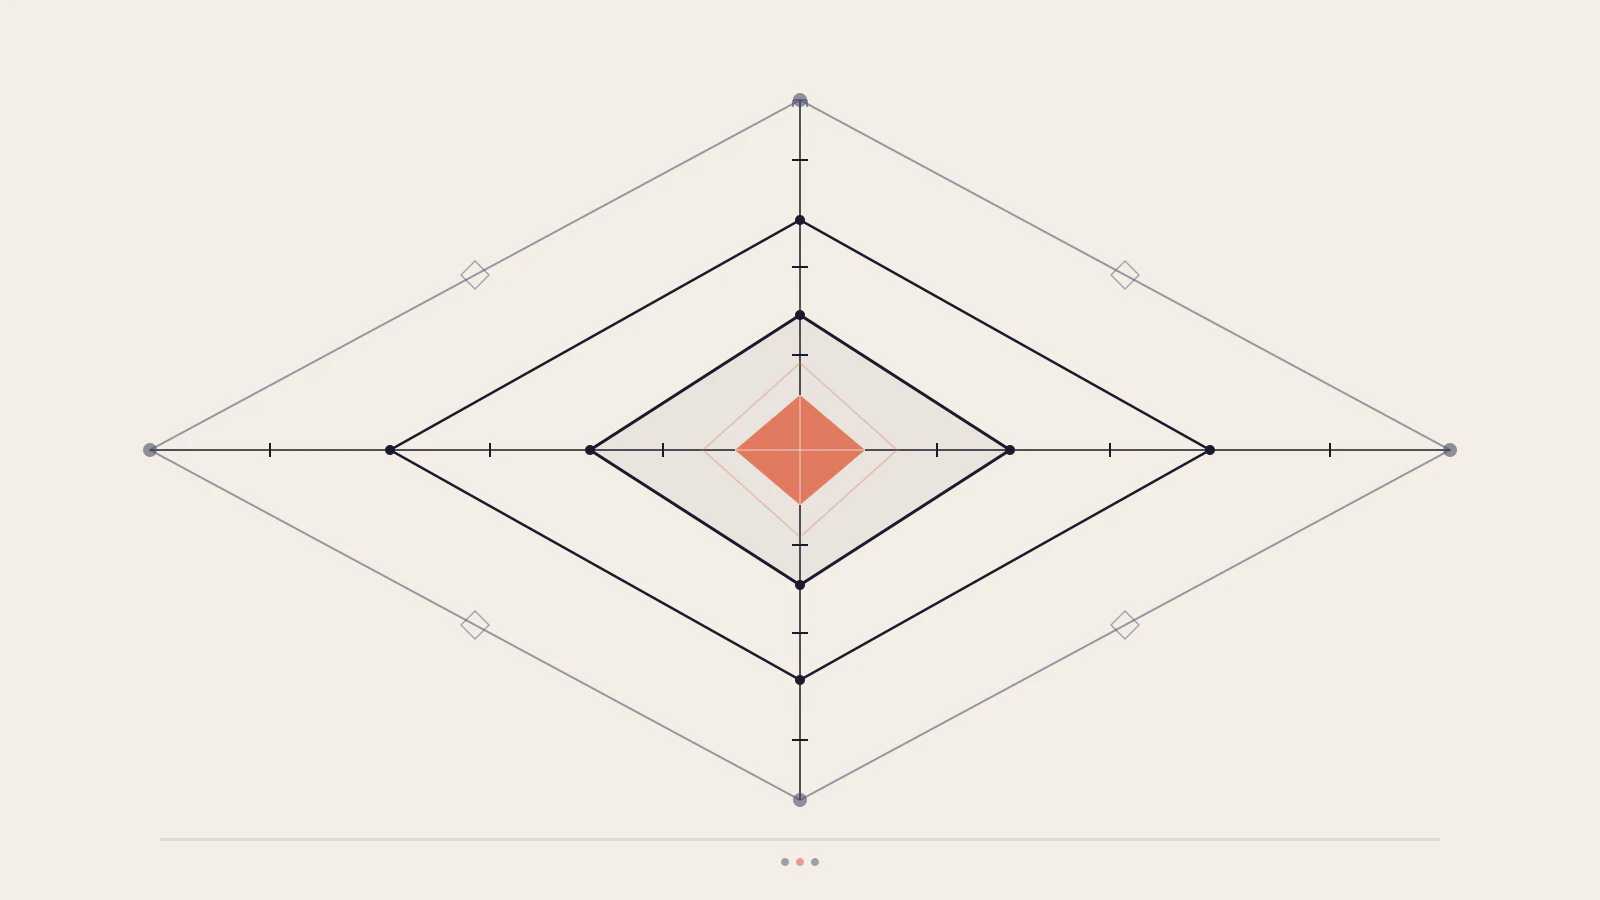
Four nested cache tiers: memory cache at the centre, application cache, CDN / HTTP cache, and the origin server at the outer ring. Requests travel inward on a hit and fall through to the next layer on a miss.