PostgreSQL vs MongoDB: Which Database Should You Choose for Your Next Project?
I compare PostgreSQL and MongoDB across data model, schema flexibility, transactions, query power, and scaling — so you can choose based on your actual situation, not the hype.
Most developers choose MongoDB because they want to skip defining a schema upfront. Most teams who regret that choice regret it for the exact same reason.
The schema question is legitimate — but it’s the wrong starting point for this decision. PostgreSQL and MongoDB make fundamentally different bets about how your data is structured, how it changes, and how it’s queried. The honest comparison starts there, not at “SQL vs NoSQL.”
I’m going to walk through the real criteria — data model, schema flexibility, transactions, query power, and scaling — and by the end you’ll have a clear framework for your situation, not a winner in the abstract.
On this page
- What the data model difference actually means
- Schema flexibility: the good and the trap
- Transactions: where the gap closed and where it didn’t
- Query power: SQL vs the aggregation pipeline
- Scaling: the honest version
- When MongoDB is the right call — and when it isn’t
- Choose based on your situation
What the data model difference actually means
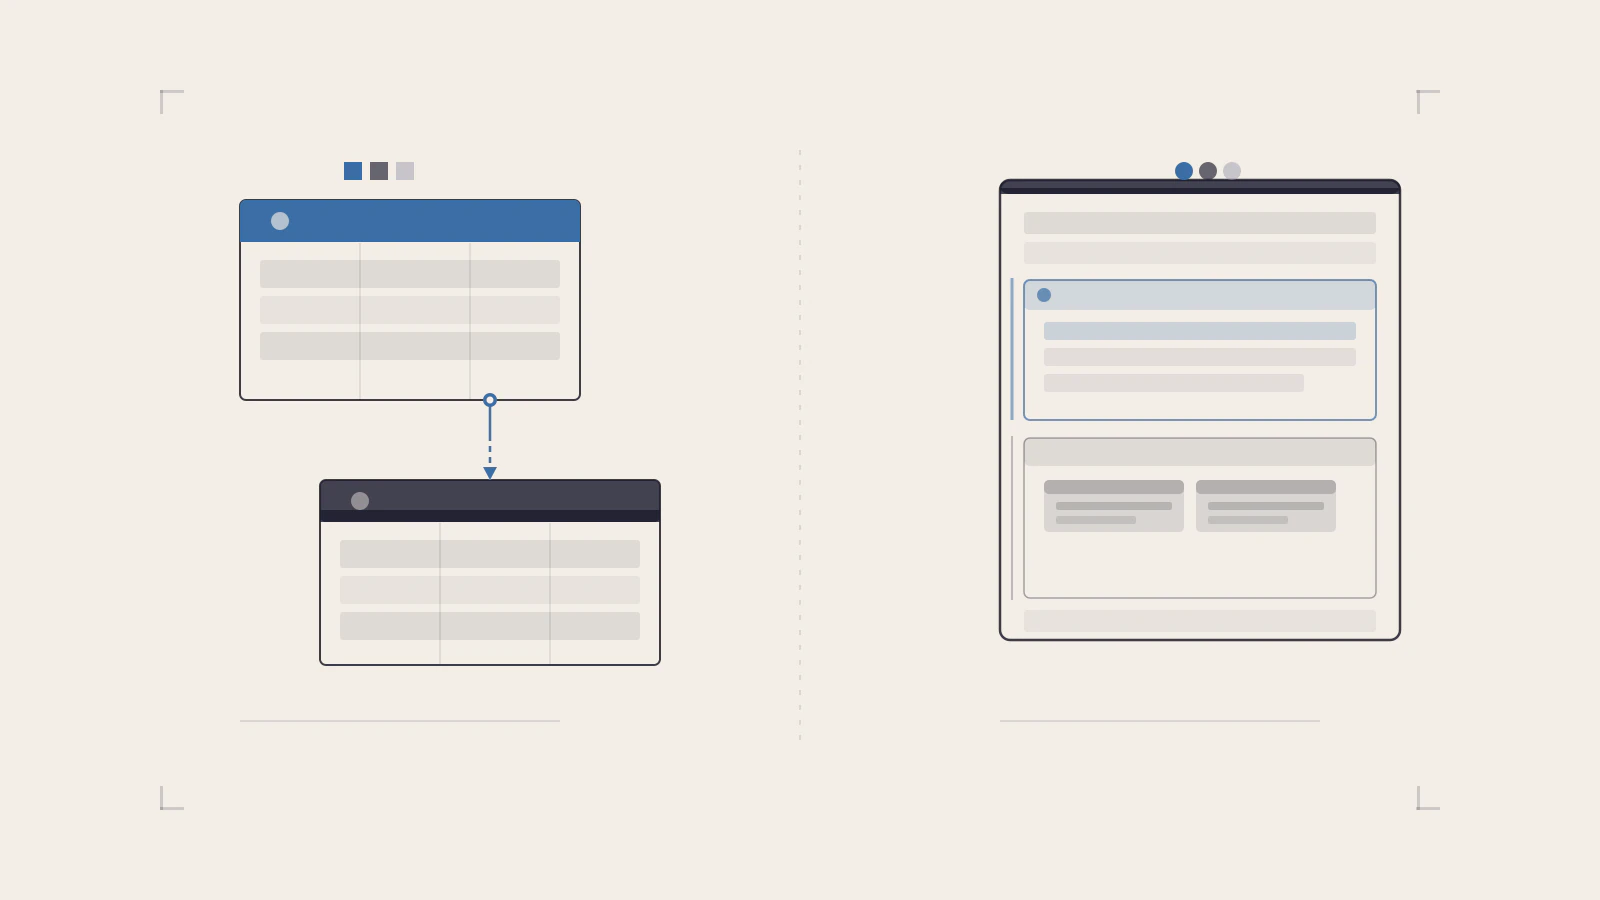
PostgreSQL is a relational database. Your data lives in tables — rows, columns, foreign keys. Relationships between entities are expressed through those keys and resolved at query time using joins. Structure is defined before you insert any data.
MongoDB is a document database. Your data lives in collections of JSON-like documents. Related data can be embedded directly inside a document — a user document might contain an array of addresses, a nested preferences object, an array of recent activity items, whatever makes sense for how you’ll retrieve it. The MongoDB documentation states the core principle plainly: “data that’s accessed together should be stored together.”
That principle drives a real difference in modelling. In a relational schema, a blog post and its tags live in separate tables joined by a junction table. In MongoDB, the tags are just an array inside the post document — one query, no join.
The trade-off: this optimisation is read-pattern-specific. Fetching a post with its tags in one shot is fast. Getting a list of all tags across all posts, or updating a tag name everywhere it appears, is less natural because the data is duplicated across documents. The relational model handles both equally well because it doesn’t duplicate.
This isn’t a flaw in either design. It’s the shape of the trade-off you’re accepting.
If you’re building your first PostgreSQL schema, the PostgreSQL for Developers post walks through tables, foreign keys, and relationships from scratch — it’s a good foundation before weighing this decision.
Schema flexibility: the good and the trap
MongoDB’s flexible schema means documents in the same collection don’t need to share the same fields or field types. You don’t write CREATE TABLE before your first insert.
The appeal is real for early-stage development. When you genuinely don’t know whether a user will have a subscription_tier field, or whether preferences will be flat or nested, being able to iterate without migrations does speed things up.
The trap arrives six months later. “Schema-less” doesn’t mean schema-free — it means schema-implicit. Your application code still expects user.email to be a string, not null, not an array. Over time, inconsistencies accumulate: old documents without the new field, a field that silently changed from a string to an object mid-deployment. Querying across these variations requires defensive code everywhere.
PostgreSQL isn’t inflexible about this either. The PostgreSQL documentation describes jsonb — a binary JSON column type stored in decomposed binary format that supports GIN indexing and containment queries. You can have a metadata jsonb column that varies freely by row while the rest of the table stays typed and constrained. That hybrid covers most legitimate “I need some looseness here” use cases without abandoning relational structure everywhere.
The honest version: if your data is genuinely and permanently schema-less — IoT payloads that vary by sensor model, a CMS where editors define custom field types — the document model is a real advantage. If your data is “schema-I-haven’t-written-yet,” PostgreSQL’s discipline will save you maintenance time.
Transactions: where the gap closed and where it didn’t
PostgreSQL has had full ACID transactions since its earliest versions. Multi-statement transactions, row-level locking, serializable snapshot isolation — they’re all there. The PostgreSQL concurrency documentation describes its MVCC model: reading never blocks writing and writing never blocks reading, even at the strictest isolation level. My post on ACID properties and isolation levels covers what these guarantees actually mean in practice.
MongoDB’s transaction story is more recent. Single-document operations have always been atomic — and for many use cases, that’s sufficient. Multi-document transactions arrived in version 4.0 for replica sets (2018) and extended to sharded clusters in 4.2 (2019). The feature exists and it works.
The important caveat comes from MongoDB’s own documentation, which says directly: “In most cases, a distributed transaction incurs a greater performance cost over single document writes, and the availability of distributed transactions should not be a replacement for effective schema design.” It follows with: “for many scenarios, the denormalized data model (embedded documents and arrays) will continue to be optimal.”
That’s the database’s own authors saying: design your documents to avoid multi-document transactions, because the cost is real. In PostgreSQL, you reach for a transaction without that warning.
If your application regularly needs to update multiple records atomically — transfer funds between accounts, decrement inventory while creating an order, update user state across two collections — PostgreSQL is the cleaner choice.
Query power: SQL vs the aggregation pipeline
SQL is a mature, declarative query language. Joins across tables, subqueries, window functions, CTEs — you can express complex relational queries that are readable, optimisable by the planner, and supported by decades of tooling. The post on database indexing and slow queries shows how PostgreSQL’s query planner uses your indexes to execute these efficiently.
MongoDB’s query model is document-first. For a single document or a filtered set, queries are straightforward. When you need cross-collection work or aggregations, you use the aggregation pipeline: a series of stages ($match, $group, $lookup, $unwind, etc.) that transform documents step by step.
The pipeline is capable and has improved with every MongoDB release. But the ergonomic gap is real. Here’s the same query — posts with their author’s name — in both:
SELECT p.title, u.name AS author_name
FROM posts p
JOIN users u ON u.id = p.user_id
WHERE p.published = true;db.posts.aggregate([
{ $match: { published: true } },
{
$lookup: {
from: "users",
localField: "user_id",
foreignField: "_id",
as: "author"
}
},
{ $unwind: "$author" },
{
$project: {
title: 1,
author_name: "$author.name"
}
}
]);Neither is wrong. But if your application is full of cross-collection queries with filtering and projections, SQL is easier to write, review, and optimise. If your access pattern is mostly “fetch this document and everything embedded in it,” the aggregation pipeline rarely comes up.
Check this before picking MongoDB for query-heavy work
- Your access patterns are document-centric — you typically need one complete document, not computed joins across collections
- Your reporting and analytics needs are handled separately, in a warehouse or a dedicated read replica
- You’ve confirmed that
$lookupwill cover the cross-collection queries you anticipate as the application grows
Scaling: the honest version
MongoDB is frequently chosen for horizontal scalability. Sharding — distributing data across multiple servers by a shard key — is a first-class feature. The architecture is designed for it.
The nuance is that sharding has real complexity costs. The MongoDB sharding documentation is direct: shard key choice is critical, and queries that don’t include the shard key become scatter-gather operations that hit every shard. A poor shard key creates hotspots that are hard to fix after data is live. Resharding exists from MongoDB 5.0, but it’s still a heavy operation.
PostgreSQL scales vertically very well. A modern cloud instance handles significant workloads, and connection pooling plus read replicas extend that further. Horizontal write sharding in PostgreSQL requires external tools, so it’s not as turnkey as MongoDB’s built-in approach.
The practical answer: most applications never reach the scale where MongoDB’s sharding advantage matters. If you’re at a startup or building a mid-size application, you’ll very likely hit other constraints before you exhaust PostgreSQL’s ceiling. If you genuinely need to scale writes across multiple machines, MongoDB’s architecture is the cleaner path.
When MongoDB is the right call — and when it isn’t
MongoDB is a good fit when:
The data is genuinely schema-less. If you’re storing IoT payloads that vary by device model, building a CMS where editors define custom fields per content type, or ingesting third-party data with unpredictable shapes — the document model maps directly to the problem. Forcing this into relational tables requires either wide sparse rows or an entity-attribute-value pattern, both of which are painful to query.
The access pattern is document-centric. An e-commerce catalogue where each product has a different attribute shape per category, or a platform where you fetch a complete user record with all embedded activity — this fits MongoDB’s “store together, read together” model well.
MongoDB is the wrong choice when:
- Your data has real relationships you’ll query across frequently. Multi-collection
$lookuppipelines at scale carry cost and complexity. - You need atomic guarantees across multiple entities regularly. Architecting around avoiding transactions is possible, but it moves complexity from the database into your application code.
- You’re storing financial, compliance-sensitive, or healthcare data. PostgreSQL’s proven ACID semantics and mature tooling are better established here.
- You want the full expressiveness of SQL — window functions, CTEs, recursive queries, complex aggregations.
One thing that doesn’t change the decision much: Prisma supports both PostgreSQL and MongoDB with a similar API surface. If you’re using an ORM, the database choice doesn’t dramatically affect your application layer. The difference shows up in schema design, query patterns, and where constraints live — not in whether you can abstract over the driver.
Choose based on your situation
No universal winner. The situational table:
| Your situation | Better fit | Reason |
|---|---|---|
| Defined relational data — users, orders, products | PostgreSQL | Foreign keys, joins, constraints, ACID without caveats |
| Genuinely schema-less content with unpredictable fields | MongoDB | Flexible documents without workarounds |
| Multi-entity atomic operations (payments, inventory, bookings) | PostgreSQL | Full ACID, no performance penalty for multi-statement transactions |
| Document-centric reads: one complete record per query | MongoDB | Embedding avoids joins, single-query retrieval |
| Complex analytical queries across many entities | PostgreSQL | SQL, window functions, CTEs, mature query planner |
| Very large write scale requiring horizontal shard-out | MongoDB | Sharding is first-class in the architecture |
| Regulated data with strong consistency requirements | PostgreSQL | Proven ACID semantics, mature compliance tooling |
| CMS or catalogue with per-record custom fields | MongoDB | Schema-less by design, not by accident |
| Mostly structured data with some flexible metadata columns | PostgreSQL + jsonb |
Relational rows, flexible JSON columns where needed |
My default is PostgreSQL. It covers an enormous range of applications, and jsonb closes most of the schema-flexibility gap for cases where some looseness genuinely helps. I’d choose MongoDB deliberately — when the data model genuinely favours documents — not as a way to avoid thinking about schema.
The choice becomes straightforward once you describe your data honestly: what it looks like, how it changes, and what questions you’ll ask of it. Start there, and the database follows.
Left: relational tables joined by a foreign key. Right: a document with embedded sub-documents. The structural difference drives every other trade-off in this comparison.