Monolith vs Microservices: Why Starting with Microservices Is Usually a Mistake
I argue that starting with microservices is a mistake for most teams, explain why the modular monolith is the smarter default, and show when distributed services genuinely earn their cost.
You’ve probably heard this pitch: microservices are how serious teams build production systems. Monoliths are what you use before you know better. At some point you’re supposed to graduate.
I used to half-believe it. Then I started paying closer attention to what teams that actually ship at scale do, and the picture looks different. Martin Fowler wrote in 2015 that “almost all the cases where I’ve heard of a system that was built as a microservice system from scratch, it has ended in serious trouble.” That’s not a fringe opinion — that’s one of the people who helped define what microservices are.
Starting with microservices isn’t bold. It’s usually just expensive.
On this page
- The complexity you’re not budgeting for
- The majestic monolith is not a compromise
- What production systems at real scale actually look like
- The modular monolith: clean boundaries, one deployment
- When microservices genuinely earn their cost
- Signs you’ve actually outgrown your monolith
- The default starting position
The complexity you’re not budgeting for
Microservices introduce a layer of distributed systems problems that doesn’t go away on its own. Service discovery. Network partitions. Distributed tracing. Eventual consistency. Retry logic and timeout budgets. API versioning contracts between services. Coordinating deployments across multiple repositories.
None of these problems are unsolvable. But every one of them takes time and tooling to address, and with microservices you’re solving them from day one — before you’ve validated whether your product is even worth building.
Fowler called this the microservice premium: the overhead of managing a suite of services rather than one application. The premium slows teams down, particularly small early ones where the same two or three people are responsible for infrastructure, features, and on-call.
Before a microservice system is production-ready, Fowler argues you need three baseline capabilities: rapid server provisioning measured in minutes, monitoring that spans all services and detects problems quickly, and a deployment pipeline that handles multiple independent deployables. Most early-stage teams have none of these on day one. Building them before you’ve shipped your first real feature is a significant bet on a domain you don’t fully understand yet.
If your team is still learning how to containerize your first app or working out your REST API design, distributed systems overhead will consume most of your development bandwidth.
The majestic monolith is not a compromise
A monolith doesn’t mean a mess. It means a single deployable unit. The code inside can be well-structured, clearly divided into modules, and easy to navigate. The “majestic monolith” idea is that a well-designed single-process application is something to be proud of, not embarrassed by.
The alternative to microservices isn’t a tangled ball of mud where every function reaches into every other. It’s a codebase with clear layers and domain separation that happens to deploy as one process.
The practical advantages are real: one test suite, one deployment pipeline, one set of infrastructure to manage. You call across module boundaries with a function call instead of an HTTP request. You don’t need to think about eventual consistency or service-to-service authentication for internal operations.
That simplicity is worth something concrete at the start: speed. You ship features faster, debug faster, and iterate faster. You focus on learning whether your product is worth building rather than on keeping nine services alive.
The tradeoff is that this simplicity has limits. It works beautifully up to a point — and then the coupling, build times, and team coordination overhead start to hurt. The question is when that point arrives, not whether it eventually does.
What production systems at real scale actually look like
The idea that monoliths can’t scale is contradicted by well-documented examples.
Stack Overflow handles more than 200 million HTTP requests per day from nine IIS web servers, a handful of SQL Server instances, Redis, and Elasticsearch. The core Q&A application is a monolith. Nick Craver noted they’ve accidentally tested running the entire site from a single web server “a few times.” The architecture isn’t complicated. It works.
This is consistent with what Fowler observed more broadly: almost all the successful microservice stories he collected “started with a monolith that got too big and was broken up.” The teams that knew their domains well enough to draw the right service boundaries had learned those domains by building a monolith first. Teams that tried to design microservices for an unfamiliar domain from scratch frequently got the boundaries wrong — and refactoring across service boundaries is significantly harder than refactoring within a single codebase.
This pattern connects directly to how systems actually scale under load. The bottleneck in early systems is rarely architecture. It’s clarity about the problem, speed of iteration, and getting real users.
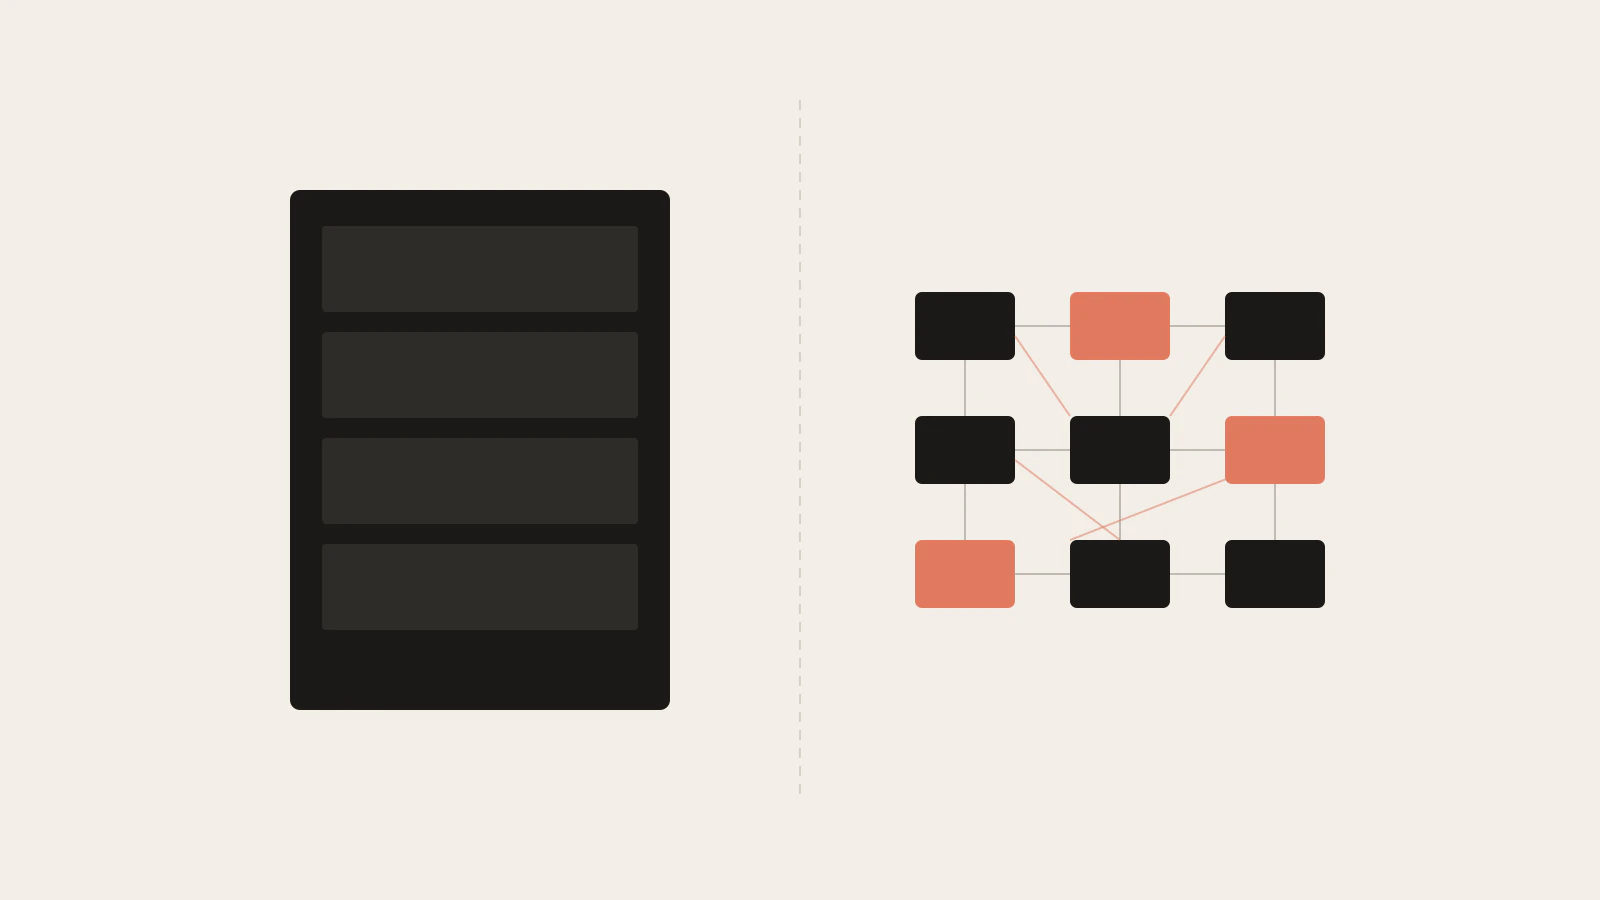
One deployment unit versus many: the complexity difference shows up in operations, not just in the codebase.
The modular monolith: clean boundaries, one deployment
There’s a middle path that most discussions skip over.
The modular monolith keeps all the code in one deployable unit but enforces strict boundaries between different domains. Each module exposes a clearly defined public API. Other modules can only call into it through that interface, never into its internals. Data ownership is explicit: one module doesn’t reach into another module’s database tables.
The result is most of the architectural clarity of microservices without the distributed systems overhead.
Shopify chose this approach around 2016-2017 when their monolith outgrew its original structure. They surveyed developers about pain points, then built a tool called Wedge to track component violations and enforce boundaries. They reorganized around 6,000 Ruby classes into clearly-owned components. They chose the modular monolith explicitly over splitting into microservices, because separate services would have introduced network latency, separate deployment pipelines, and infrastructure overhead they didn’t want to absorb. Their account is worth reading in full.
The modular monolith lets you build the domain boundaries first, gain real clarity on where the seams should be, and later extract the pieces that genuinely need independent scaling or deployment. That’s a much less risky path than designing service boundaries for a domain you’re still discovering.
When microservices genuinely earn their cost
Microservices aren’t wrong. They’re expensive — and sometimes that cost is worth paying.
| Situation | Microservices justified? | Why |
|---|---|---|
| Multiple teams deploying independently | Yes | Separate repos and pipelines remove cross-team coordination from the critical path |
| Genuinely different tech needs per component | Yes | A compiled service for heavy compute, a scripted service for real-time events |
| Parts of the system need to scale independently | Yes | Targeted scaling without scaling the whole application |
| Domain boundaries are well-understood and stable | Yes | Wrong boundaries require painful cross-service refactors |
| Early-stage product still finding product-market fit | No | Iteration speed matters more than independent deployment |
| Team of five or fewer engineers | No | The operational overhead is proportionally much higher |
| Domain model isn’t proven yet | No | Getting the boundaries wrong is expensive to fix later |
The strongest legitimate case for microservices is team autonomy at scale. Conway’s Law is real: the structure of your system tends to reflect the organization that built it. When you have many independent teams that need to ship without coordinating every deployment, microservices make that coordination explicit and manageable through contracts rather than hidden through shared code. That’s an organizational problem solved by an architectural choice — it doesn’t apply to a team of four.
Independent deployment cadences are the other genuine driver. If your payment processing component genuinely needs to be updated without touching the rest of the application, that’s a real reason to separate them — once you have the infrastructure to manage it reliably. When you’re already running Kubernetes with rolling deployments and health checks, the overhead of independent services is much lower than it would be otherwise.
The counterargument to monolith-first is worth taking seriously: starting with microservices forces the team to get comfortable with distributed systems from the beginning, and it’s harder to retrofit the discipline later. Fowler acknowledges this case, particularly for teams replacing an existing system where the domain is already well-understood. The honest answer is that this works if your team has prior microservice experience. If you don’t, you’ll spend most of your time on infrastructure rather than product.
Signs you’ve actually outgrown your monolith
There’s a real difference between “this is getting complex” and “we need microservices.” Here’s what the actual tipping point looks like:
- Build and test times are blocking delivery. Not “a bit slow” — slow enough that a small change takes an hour to validate and you’re skipping tests to ship.
- Coupling that can’t be reduced through refactoring. If two domains are so tangled that you can’t draw a clean interface boundary even in code, that’s a structural problem a module boundary won’t solve without real separation.
- Genuinely different scaling requirements. Your high-traffic read API doesn’t need to scale with your nightly batch jobs.
- Teams spending more time coordinating than building. If the main cost is merge conflicts and deployment coordination across a large team, service boundaries reduce that by making the coordination explicit.
Notice what’s not on that list: “we’re growing fast,” “we want to say we use microservices,” or “we want to hire people who know Kubernetes.” None of those are architectural problems that a distributed system solves.
The default starting position
Start with a monolith. Design it well — clear module boundaries, explicit data ownership per domain, a thoughtful API structure for external consumers. Pay attention to where the natural seams are as your domain knowledge grows.
When you find yourself hitting the problems above — genuinely blocked build times, coupling you can’t refactor away, real scaling asymmetries, or team coordination costs that outweigh the benefits of a shared codebase — that’s when the complexity of microservices starts to pay off. Peel off one service first, learn what running a distributed system actually costs your team, and grow the architecture from there.
The biggest risk isn’t moving too slowly toward microservices. It’s starting with a distributed architecture before you understand your domain well enough to draw the right boundaries.
Fowler’s framing has held up since 2015: “don’t even consider microservices unless you have a system that’s too complex to manage as a monolith.” That’s not a conservative opinion. It’s pattern-matching on what actually works in practice.